
L’articolo è stato aggiunto alla lista dei desideri



EBOOK IN LINGUA STRANIERA
 E-mail
 Facebook
 LinkedIn
 Twitter
 WhatsApp
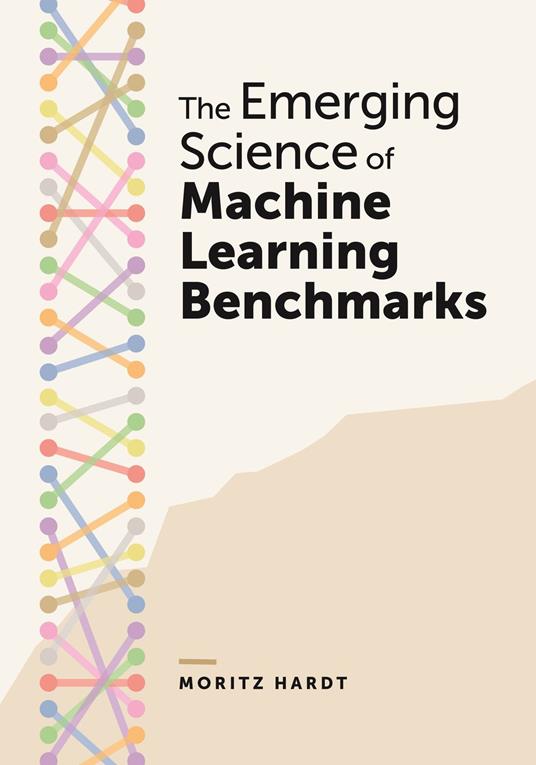
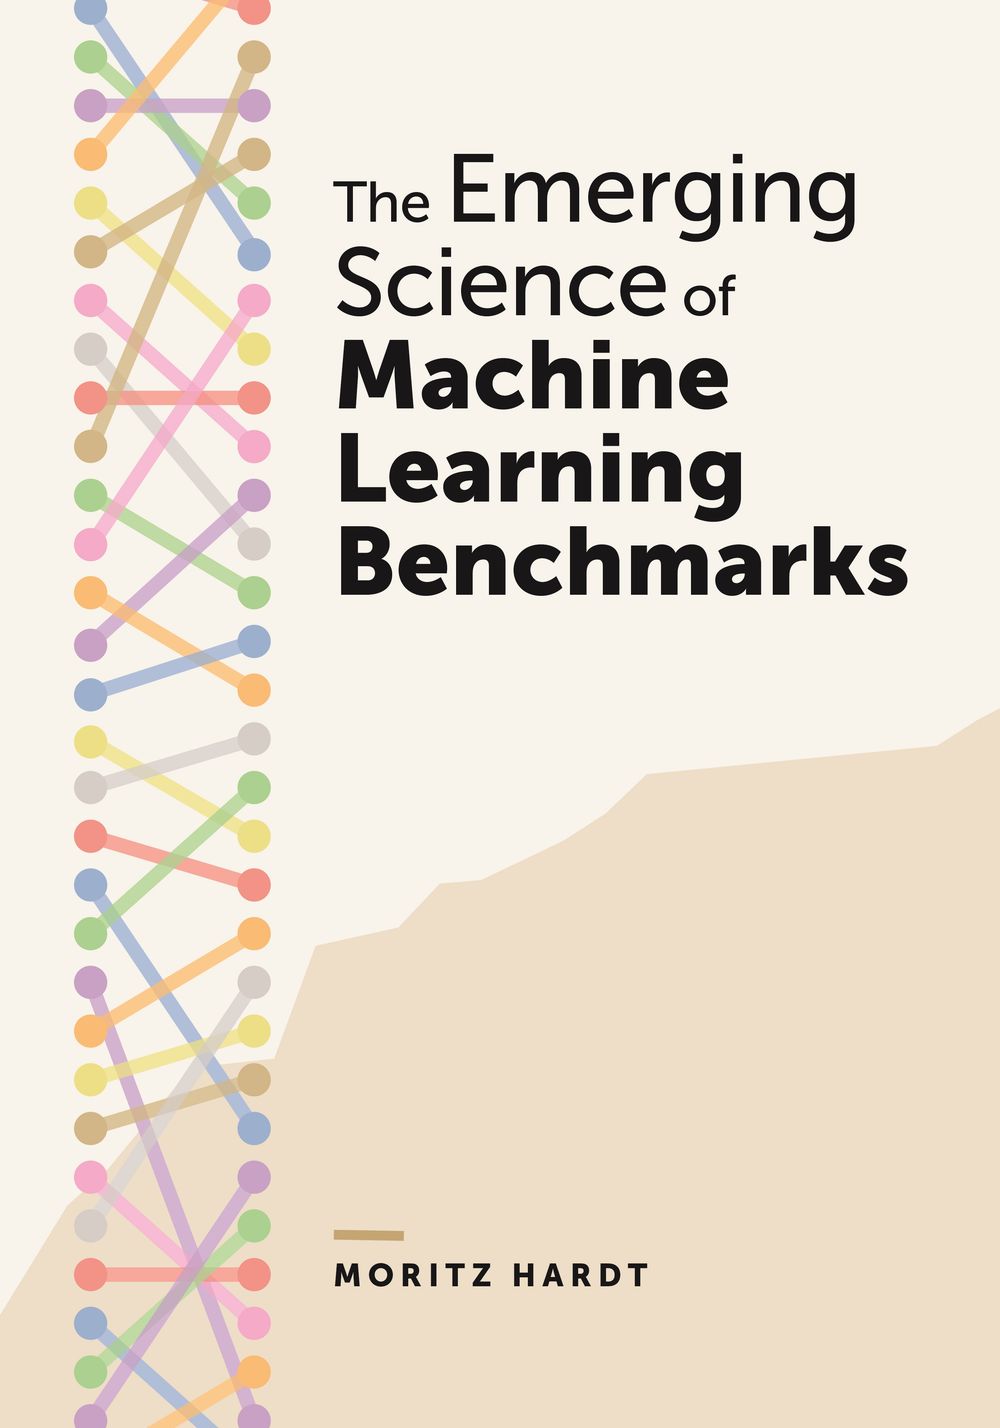
The Emerging Science of Machine Learning Benchmarks
(0)
Cliccando su “Conferma” dichiari che il contenuto da te inserito è conforme alle Condizioni Generali d’Uso del Sito ed alle Linee Guida sui Contenuti Vietati. Puoi rileggere e modificare e successivamente confermare il tuo contenuto. Tra poche ore lo troverai online (in caso contrario verifica la conformità del contenuto alle policy del Sito).
Grazie per la tua recensione!
Tra poche ore la vedrai online (in caso contrario verifica la conformità del testo alle nostre linee guida). Dopo la pubblicazione per te +4 punti 
33,27 €

Venditore: IBS

Acquista online
Scaricabile subito
Articolo acquistabile con Carta del Docente

Articolo acquistabile con Carta Cultura Giovani e Carta del Merito
Articolo acquistabile con Carta della Cultura

Dati e Statistiche
 Salvato in 0 liste dei desideri
The Emerging Science of Machine Learning Benchmarks
Scaricabile subito
33,27 €
33,27 €
Scaricabile subito
Altre offerte vendute e spedite dai nostri venditori
Ebook in lingua straniera
The Emerging Science of Machine Learning Benchmarks
Altri venditori
Prezzo e spese di spedizione
EBOOK INGLESE
EPUB3 con Adobe DRM
Scaricabile subito
Venduto e spedito da
IBS
Spedizione Gratis
33,27 €
Altri venditori
Prezzo e spese di spedizione
EBOOK INGLESE
EPUB3 con Adobe DRM
Scaricabile subito
Venduto e spedito da
IBS
Spedizione Gratis
33,27 €
Altri venditori
Prezzo e spese di spedizione

Tutti i formati ed edizioni
Promo attive (0)
The Emerging Science of Machine Learning Benchmarks
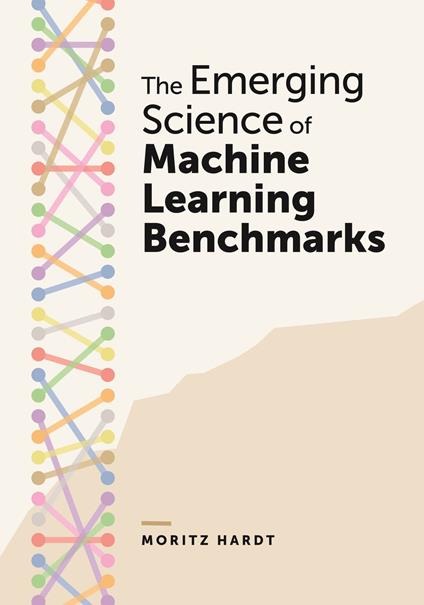
The first comprehensive introduction to benchmarking, the engine behind progress in AI In machine learning, researchers split their data into training and test sets, let model builders compete on the test set, and call it a benchmark. Statistical tradition prescribed locking test sets in a vault, but machine learning practitioners shared them freely. Benchmarking shouldn’t have worked, but it did, and the machine learning community never figured out the science behind it. How did benchmarking, despite its flaws, lead to advances in AI? In The Emerging Science of Machine Learning Benchmarks, Moritz Hardt investigates why benchmarking works, and what purpose it serves. Hardt draws on a growing body of work that has begun to lay out the science underpinning benchmarks; what emerges is a rich landscape of theoretical and empirical observations that can inform practitioners. He begins with the foundations, both mathematical and empirical, covering enough background material to make the book self-contained. He finds that model rankings, rather than model evaluation, are the primary scientific product of machine learning benchmarks. Turning to the challenges of benchmarking large language models, Hardt explains how benchmarks influence model training, complicating direct model comparisons. As model capabilities exceed those of human evaluators, researchers are running out of ways to test new models. If benchmarks are to serve us well in the future, we must place them on solid scientific ground. With this book, Hardt lays the foundation.
Leggi di più
Leggi di meno
Autore:
Anno edizione:
2026
Editore:
Formato:
Lingua:
Inglese
Compatibilità:
Tutti i dispositivi (eccetto Kindle) Scopri di più
Layout:
Reflowable
EAN:
9780691298818
L'articolo è stato aggiunto al carrello
Formato:
Gli eBook venduti da IBS.it sono in formato ePub e possono essere protetti da Adobe DRM. In caso di download di un file protetto da DRM si otterrà un file in formato .acs, (Adobe Content Server Message), che dovrà essere aperto tramite Adobe Digital Editions e autorizzato tramite un account Adobe, prima di poter essere letto su pc o trasferito su dispositivi compatibili.
Cloud:
Gli eBook venduti da IBS.it sono sincronizzati automaticamente su tutti i client di lettura Kobo successivamente all’acquisto. Grazie al Cloud Kobo i progressi di lettura, le note, le evidenziazioni vengono salvati e sincronizzati automaticamente su tutti i dispositivi e le APP di lettura Kobo utilizzati per la lettura.
Clicca qui per sapere come scaricare gli ebook utilizzando un pc con sistema operativo Windows
L’articolo è stato aggiunto alla lista dei desideri
